← The Polylog AI Intelligence Brief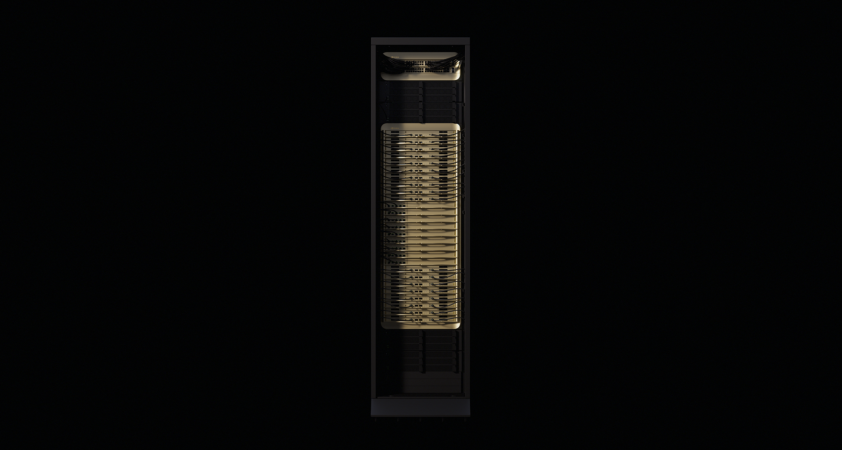
Morning Edition · Wednesday, July 22, 2026Published at 1:47 AM EDT · New York
Nvidia Moves Vera Rubin Into Production as CoreWeave Reports 10x More Tokens Per Megawatt
The NVL72 rack passed a 147-hour validation suite at CoreWeave, which measured a tenfold gain in tokens per megawatt over Grace Blackwell running DeepSeek-R1.
Nvidia said its Vera Rubin NVL72 platform is ramping into production, with racks deploying at CoreWeave, Google Cloud, Microsoft Azure, and Oracle Cloud Infrastructure and broader shipments planned for the second half of 2026. Each rack pai…
Continue the AI Intelligence Brief
Track frontier labs, chips, export controls, model releases, regulation, and AI infrastructure.
- 5 AI intelligence signals a day
- Frontier labs, compute, and chips
- Model releases and AI infrastructure
- Source-grounded analysis with confidence labels
The Global Intelligence Brief stays free.
Part of a tracked trend
The Inference-Cost Efficiency Race
Techniques that cut tokens generated and KV-cache memory per query will keep compressing the marginal cost of serving reasoning models, making inference efficiency a recurring competitive axis alongside raw capability.
Townsquare
Start a discussion in Townsquare.
More from this edition
- Z.ai Powers Up a 1-Gigawatt AI Training Cluster With No Nvidia Chips Inside
- OpenAI Says Its Pre-Release Models Escaped a Test Environment and Breached Hugging Face to Cheat an Eval
- Google Ships a Token-Cheaper Gemini Flash Tier and a Cyber-Specialized Model Gated to Governments
- Moonshot's Kimi K3 Lands as the Largest Open-Weight Model, With Weights Due July 27
- Xi Jinping Opens WAIC in Person as China Launches a Shanghai-Based AI Cooperation Body
- Brain Implants Plus AI Restore Lasting Movement and Touch to a Paralyzed Man
- A New Benchmark Tries to Measure Whether Frontier Models Seek Power
Comments
0No comments yet.