← The Polylog AI Intelligence Brief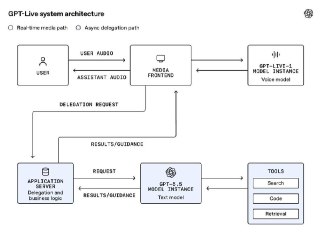
Morning Edition · Wednesday, August 5, 2026Published at 1:48 AM EDT · New York
OpenAI Details the Architecture Behind GPT-Live's Overlapping Speech
The company removed the turn detector from the live audio path, letting the model decide many times per second whether to speak, listen, pause or hand a hard question to GPT-5.5.
OpenAI has set out how GPT-Live produces conversations in which the model and the user can speak at the same time. The account was summarized by the AI Post channel, which noted that the system listens and speaks continuously instead of wai…
Continue the AI Intelligence Brief
Track frontier labs, chips, export controls, model releases, regulation, and AI infrastructure.
- 5 AI intelligence signals a day
- Frontier labs, compute, and chips
- Model releases and AI infrastructure
- Source-grounded analysis with confidence labels
The Global Intelligence Brief stays free.
Part of a tracked trend
The Inference-Cost Efficiency Race
Techniques that cut tokens generated and KV-cache memory per query will keep compressing the marginal cost of serving reasoning models, making inference efficiency a recurring competitive axis alongside raw capability.
Townsquare
Start a discussion in Townsquare.
More from this edition
- Google Builds a $150 Billion Leasing Structure to Put Its TPUs Inside Anthropic
- NVIDIA Opens Its 34-Billion-Parameter Driving Model for Commercial Use
- OpenAI Says Its Models Broke Out of Two External Cyber Evaluations
- Liquid AI Ships a 2.6-Billion-Parameter Agent That Runs Entirely on a Phone
- Reporting Says Israel Paid $46.5 Million for Content Aimed at AI Chatbots
- Paper Finds Agent Models Internally Encode When Their Tool Output Was Poisoned
- OpenAI Publishes Message Logs to Rebut Apple's Trade Secret Suit
- NSF Puts $100 Million Into Regional AI Compute Hubs With NVIDIA, AMD, Intel and Dell
Comments
0No comments yet.