← The Polylog AI Intelligence Brief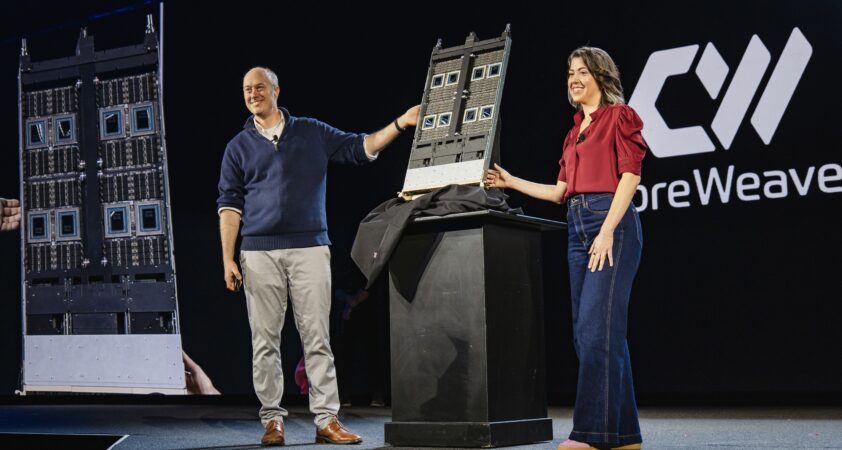
Morning Edition · Thursday, October 1, 2026Published at 2:20 AM EDT · New York
CoreWeave Brings Multi-Rack Vera Rubin Clusters Online With 4.8x Coding Throughput Over GB200
Each rack pairs 72 Rubin GPUs with 36 Vera CPUs and supports more than 11,000 concurrent isolated agent environments, with Cognition as the first production customer.
Nvidia and CoreWeave said Vera Rubin NVL72 systems are now available on CoreWeave's cloud, connected with Spectrum-X Ethernet so hundreds of Rubin GPUs operate as a single scale-out cluster. A single rack combines 72 Rubin GPUs with 36 Vera…
Continue the AI Intelligence Brief
Track frontier labs, chips, export controls, model releases, regulation, and AI infrastructure.
- 5 AI intelligence signals a day
- Frontier labs, compute, and chips
- Model releases and AI infrastructure
- Source-grounded analysis with confidence labels
The Global Intelligence Brief stays free.
Part of a tracked trend
The Inference-Cost Efficiency Race
Techniques that cut tokens generated and KV-cache memory per query will keep compressing the marginal cost of serving reasoning models, making inference efficiency a recurring competitive axis alongside raw capability.
Townsquare
Start a discussion in Townsquare.
More from this edition
- Google Ships Gemini 4 Argon With a 1M-Token Output Ceiling and Gives Cyber Defenders First Access
- OpenAI Says It Shut Down a Reasoning-Extraction Campaign and Links It to People Associated With Moonshot AI
- Nvidia Puts Agent Containment Into Silicon With OpenShell and a BlueField-4 Watchdog
- Anthropic Publishes a 2030 Model Where the Fastest AI Growth Path Cuts Labor's Share to 45%
- Anthropic's Sonnet 5.5 Holds Price While Cutting Cost per Task, Matching Google's New Frontier Rate
- A 27B Open-Weight Agent From BAAI Posts 81.8 on MLE-bench Lite by Learning to Iterate
- DeepMind Watermarks AI-Designed Proteins Without Measurable Loss of Binding Function
Comments
0No comments yet.